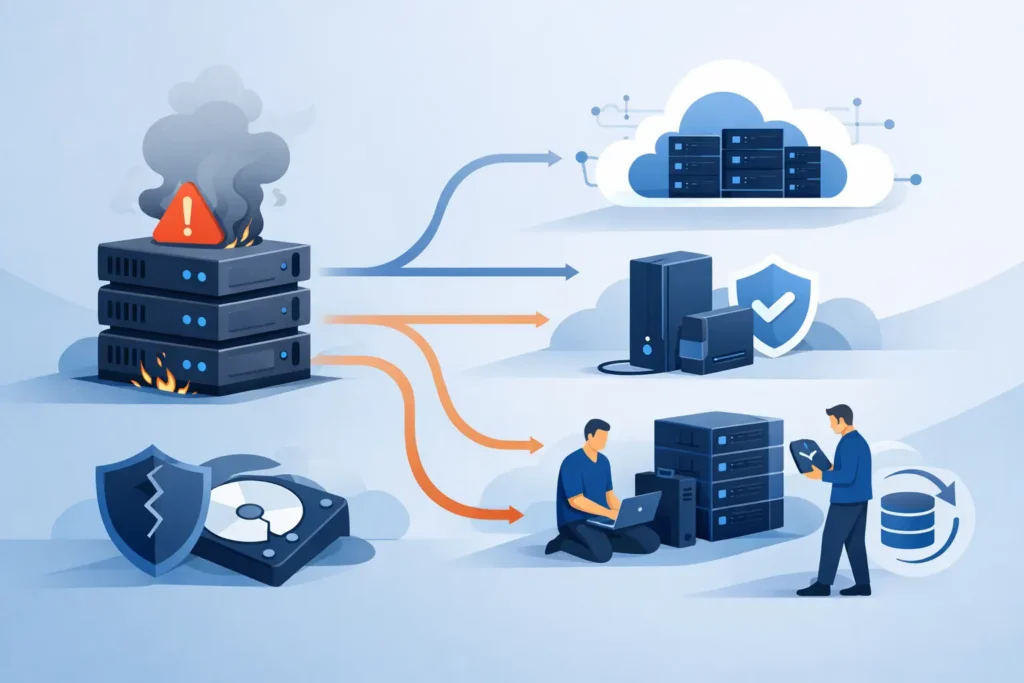
A server fails at 08:12, payroll is due, customer records are unavailable, and someone suggests restarting it until it works. That decision can determine whether the incident remains a short outage or becomes a permanent data-loss event. The best options for failed servers depend on what has failed, whether the data is still accessible elsewhere, and how much risk the organisation can accept.
A server is not just one piece of hardware. It may contain multiple disks, a RAID controller, a virtual machine host, encrypted volumes, databases and years of business files. Treating every fault as a simple IT support issue is where recoverable data is often lost.
First, separate downtime from data loss
A failed server can still hold intact data. Equally, a server that appears to start normally can be corrupting data in the background. Before choosing a response, establish whether the immediate problem is availability, hardware failure, logical corruption or a security incident.
If users cannot connect but the storage remains healthy, a network, authentication, application or operating-system fault may be responsible. A controlled restart or failover to a standby system may be reasonable if verified backups exist and the server is not reporting disk errors.
If the server will not boot, reports missing RAID volumes, clicks or repeatedly spins down, displays a degraded array, or has been dropped, exposed to water or affected by a power event, stop. Repeated restarts, rebuild attempts and improvised disk swaps can overwrite the very information needed to reconstruct the data.
The priority is to preserve the current state. Record error messages, take photographs of disk order and cabling, and note any recent events such as a power cut, firmware update, failed drive replacement or ransomware alert. Do not initialise disks, create a new array or accept a prompt to format a volume.
Best options for failed servers by scenario
There is no single correct recovery route. The right option is the one that restores service without making the underlying loss worse.
Restore from a tested backup
A clean, recent and tested backup is normally the fastest route back to operation. This is especially true where the server hardware has failed but backups are held separately and can be restored to replacement hardware, a virtual environment or a temporary hosted platform.
However, backup restoration has limits. The backup may be incomplete, old, encrypted with an unavailable key, or connected to the same ransomware incident. Check the restoration point before committing to it. For a business database, the difference between last night’s backup and the most recent transaction logs can represent a full day of lost orders, case notes or accounts data.
Where backups are sound, restore to separate storage first where practical. This avoids writing over the original server disks before the restored data has been checked by the relevant department.
Fail over to a replica or standby server
Businesses with high availability systems may be able to bring up a replica, clustered node or disaster recovery environment. This can sharply reduce downtime, but it is not automatically safe. Replication can copy corruption, accidental deletion or ransomware encryption as efficiently as it copies healthy data.
Confirm the last known good point and isolate the failed source before allowing any automatic synchronisation to resume. A fast failover is valuable, but only if the replacement environment is not inheriting the same fault.
Repair the server software or virtual environment
If diagnostics show the disks and storage pool are healthy, an experienced administrator may repair the operating system, application service, hypervisor configuration or virtual machine files. Typical examples include a failed Windows update, damaged boot configuration, corrupted Active Directory service or a virtual host that cannot mount a datastore.
This option is appropriate when there is a verified backup and a clear recovery plan. It is less suitable when the storage itself is degraded. Software repair commands can write to disks, journal file systems or alter metadata. Once those changes occur, specialist recovery becomes more difficult.
Rebuild a degraded RAID array with caution
A RAID array is designed to tolerate certain drive failures, not every failure. RAID 5 can survive one failed disk; RAID 6 can survive two. But a second failure, unreadable sectors on another member disk, incorrect disk order or an interrupted rebuild can make the array inaccessible.
A rebuild writes data across the remaining disks. If the RAID controller has misidentified a drive, the array configuration is uncertain, or more disks are degraded than the system reports, rebuilding can overwrite parity and metadata required for recovery. Never assume that a “rebuild recommended” message means rebuilding is safe.
Professional RAID recovery begins by creating sector-level images of each available disk and analysing the array configuration without altering the originals. Stripe size, disk order, parity rotation, controller behaviour and file-system structure must all be accounted for before data extraction begins.
Use specialist server data recovery
When disks have failed mechanically, SSDs have controller or firmware faults, the RAID is offline, volumes are encrypted or a rebuild has gone wrong, specialist recovery is usually the safest option. This is also the right route where the data is commercially, legally or personally irreplaceable.
A properly equipped lab can assess individual drives, work from forensic images rather than live media, reconstruct RAID and SAN configurations, repair logical structures and extract priority data first where feasible. For critical cases, the question is not simply whether files can be recovered. It is whether the process protects confidentiality, evidential integrity and the remaining chance of a successful outcome.
Data Recovery Lab provides free collection and assessment, works from a real London laboratory, and follows a no-recovery, no-fee model. That matters when a failed server contains client records, legal documents, financial data, CCTV footage or intellectual property that cannot be entrusted to an unverified repair service.
What not to do after a server failure
Pressure encourages shortcuts. Avoid these common actions until you understand the fault:
- Do not keep rebooting a server with failing disks or unusual noises.
- Do not run repair utilities against the only copy of important data.
- Do not replace several RAID disks at once or change their physical order.
- Do not initialise, format or create a new array when prompted by the controller.
- Do not allow an unqualified third party to experiment with confidential disks.
The same caution applies to SSD-based servers. SSD failures can be sudden, and power cycling may trigger internal processes that change the state of the drive. Encryption, wear levelling and proprietary controllers make DIY recovery particularly unpredictable.
How to make the recovery decision
Start with three questions. Is there a verified backup that meets the required recovery point? Is the original storage showing physical or RAID-level failure? And what is the cost of losing the newest data versus the cost of extended downtime?
For a non-critical file server with a proven backup from the previous evening, replacement hardware and restoration may be the sensible business decision. For an accounting server during year-end, a legal case management system, a production database or a NAS containing the only copy of active project work, preserving the original media and pursuing recovery may be justified even if a partial backup exists.
Businesses should also consider the data protection implications. Failed servers frequently contain personal data, commercial contracts and sensitive correspondence. Secure collection, controlled access, documented handling and GDPR-compliant confidentiality are operational requirements, not optional extras.
Prevent the next server incident
Once service is restored, investigate why the failure occurred. Check whether monitoring detected disk warnings, whether backups can be restored within the required timeframe, and whether the server had a single point of failure. Test recovery procedures under realistic conditions rather than relying on a successful backup notification.
Keep replacement hardware plans current, document RAID layouts and encryption keys, and ensure the people responsible for an incident know when to stop troubleshooting. The most effective disaster recovery plan is one that protects data before an engineer is forced to make a decision under pressure.
A failed server does not always mean lost data. The careful response is to stabilise the situation, protect the original storage and choose the recovery path that preserves both the information and the organisation relying on it.
